Taras Trishchuk · November 2026 · Infographic | Українська
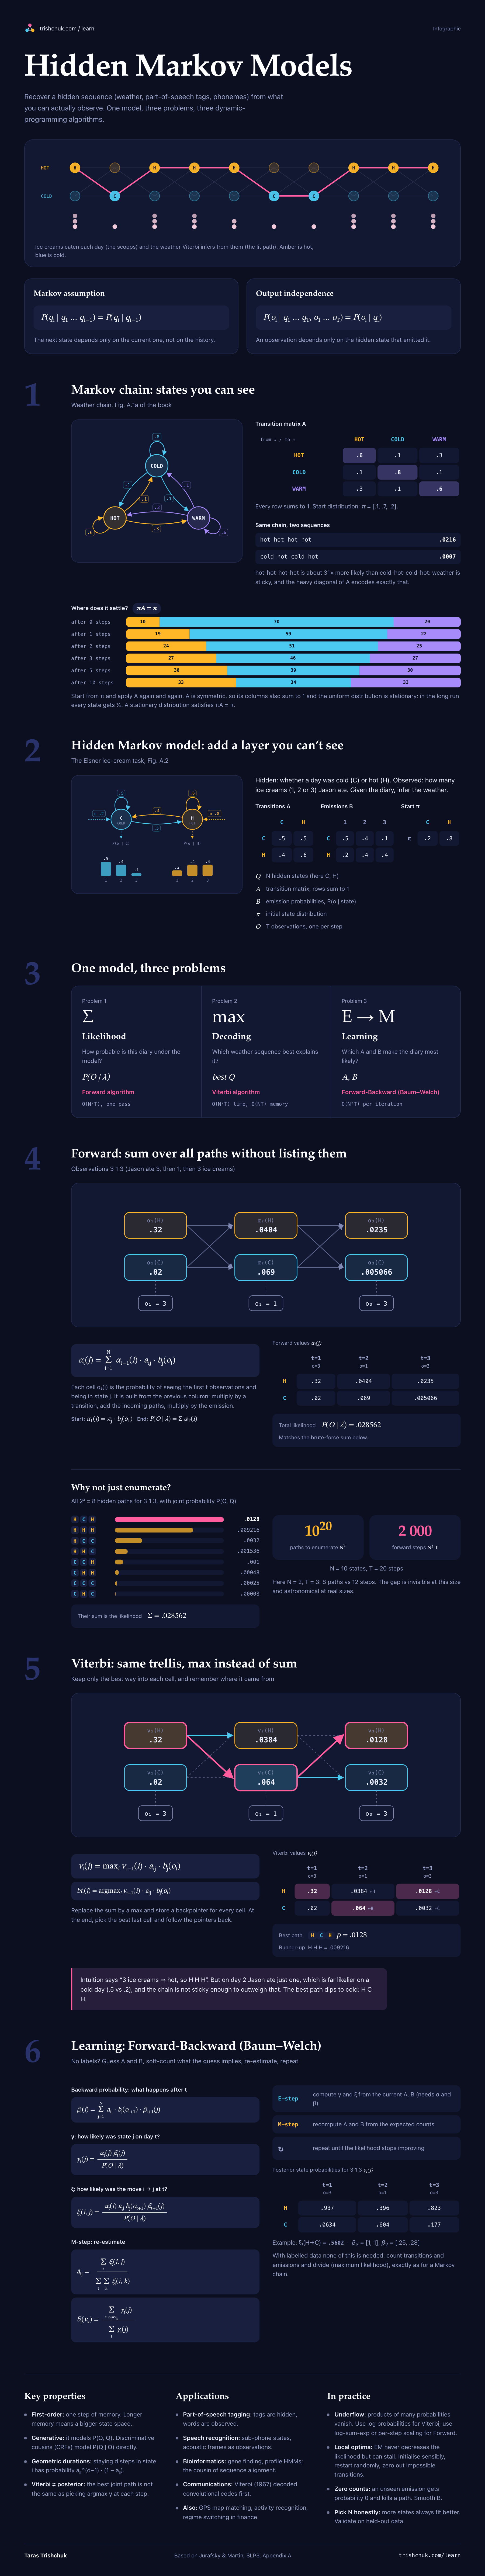
You see the ice creams someone ate; you want the weather. A hidden Markov model (HMM) is the smallest honest model of that situation: a chain of hidden states that you cannot see, each of which emits something you can. This poster walks the whole story from the Markov chain to training, using one tiny example so that every number can be checked by hand.
Everything on the poster is computed by the same code that powers the calculator below it, not copied from a figure. The example and the three-problem framing follow Appendix A of Jurafsky & Martin; the commentary and the practice notes are mine.
trishchuk.com / learn
Infographic
Hidden Markov Models
Recover a hidden sequence (weather, part-of-speech tags, phonemes) from what you can actually observe. One model, three problems, three dynamic-programming algorithms.
Ice creams eaten each day (the scoops) and the weather Viterbi infers from them (the lit path). Amber is hot, blue is cold.
Markov assumption
P(qi | q1 … qi−1) = P(qi | qi−1)
The next state depends only on the current one, not on the history.
Output independence
P(oi | q1 … qT, o1 … oT) = P(oi | qi)
An observation depends only on the hidden state that emitted it.
1
Markov chain: states you can see
Weather chain, Fig. A.1a of the book
Transition matrix A
from ↓ / to →
HOT
COLD
WARM
HOT
.6
.1
.3
COLD
.1
.8
.1
WARM
.3
.1
.6
Every row sums to 1. Start distribution: π = [.1, .7, .2].
Same chain, two sequences
hot hot hot hot.0216
cold hot cold hot.0007
hot-hot-hot-hot is about 31× more likely than cold-hot-cold-hot: weather is sticky, and the heavy diagonal of A encodes exactly that.
Where does it settle? πA = π
after 0 steps107020
after 1 steps195922
after 2 steps245125
after 3 steps274627
after 5 steps303930
after 10 steps333433
Start from π and apply A again and again. A is symmetric, so its columns also sum to 1 and the uniform distribution is stationary: in the long run every state gets ⅓. A stationary distribution satisfies πA = π.
2
Hidden Markov model: add a layer you can’t see
The Eisner ice-cream task, Fig. A.2
Hidden: whether a day was cold (C) or hot (H). Observed: how many ice creams (1, 2 or 3) Jason ate. Given the diary, infer the weather.
Transitions A
C
H
C
.5
.5
H
.4
.6
Emissions B
1
2
3
C
.5
.4
.1
H
.2
.4
.4
Start π
C
H
π
.2
.8
Q
N hidden states (here C, H)
A
transition matrix, rows sum to 1
B
emission probabilities, P(o | state)
π
initial state distribution
O
T observations, one per step
3
One model, three problems
Problem 1
Σ
Likelihood
How probable is this diary under the model?
P(O | λ)
Forward algorithm
O(N²T), one pass
Problem 2
max
Decoding
Which weather sequence best explains it?
best Q
Viterbi algorithm
O(N²T) time, O(NT) memory
Problem 3
E → M
Learning
Which A and B make the diary most likely?
A, B
Forward-Backward (Baum–Welch)
O(N²T) per iteration
4
Forward: sum over all paths without listing them
Observations 3 1 3 (Jason ate 3, then 1, then 3 ice creams)
αt(j) = NΣi=1αt−1(i) · aij · bj(ot)
Each cell αₜ(j) is the probability of seeing the first t observations and being in state j. It is built from the previous column: multiply by a transition, add the incoming paths, multiply by the emission.
Start:α1(j) = πj · bj(o1) End:P(O | λ) = Σ αT(i)
Forward values αt(j)
t=1 o=3
t=2 o=1
t=3 o=3
H
.32
.0404
.0235
C
.02
.069
.005066
Total likelihoodP(O | λ) = .028562Matches the brute-force sum below.
Why not just enumerate?
All 2³ = 8 hidden paths for 3 1 3, with joint probability P(O, Q)
HCH.0128
HHH.009216
HCC.0032
HHC.001536
CCH.001
CHH.00048
CCC.00025
CHC.00008
Their sum is the likelihoodΣ = .028562
1020paths to enumerate NT
2 000forward steps N²·T
N = 10 states, T = 20 steps
Here N = 2, T = 3: 8 paths vs 12 steps. The gap is invisible at this size and astronomical at real sizes.
5
Viterbi: same trellis, max instead of sum
Keep only the best way into each cell, and remember where it came from
vt(j) = maxivt−1(i) · aij · bj(ot)
btt(j) = argmaxivt−1(i) · aij · bj(ot)
Replace the sum by a max and store a backpointer for every cell. At the end, pick the best last cell and follow the pointers back.
Viterbi values vt(j)
t=1 o=3
t=2 o=1
t=3 o=3
H
.32
.0384←H
.0128←C
C
.02
.064←H
.0032←C
Best pathHCHp = .0128Runner-up: H H H = .009216
Intuition says “3 ice creams ⇒ hot, so H H H”. But on day 2 Jason ate just one, which is far likelier on a cold day (.5 vs .2), and the chain is not sticky enough to outweigh that. The best path dips to cold: H C H.
6
Learning: Forward-Backward (Baum–Welch)
No labels? Guess A and B, soft-count what the guess implies, re-estimate, repeat
Backward probability: what happens after t
βt(i) = NΣj=1aij · bj(ot+1) · βt+1(j)
γ: how likely was state j on day t?
γt(j) = αt(j) βt(j) / P(O | λ)
ξ: how likely was the move i → j at t?
ξt(i, j) = αt(i) aijbj(ot+1) βt+1(j) / P(O | λ)
M-step: re-estimate
âij = Σtξt(i, j) / ΣtΣkξt(i, k)
b̂j(vk) = Σt: ot=vkγt(j) / Σtγt(j)
E-stepcompute γ and ξ from the current A, B (needs α and β)
L. R. Rabiner (1989), A tutorial on hidden Markov models and selected applications in speech recognition, Proc. IEEE 77(2). The classic tutorial.
J. Eisner (2002), An interactive spreadsheet for teaching the forward-backward algorithm. Origin of the ice-cream task.
A. J. Viterbi (1967), Error bounds for convolutional codes and an asymptotically optimum decoding algorithm. L. E. Baum et al. (1966–72) for the forward-backward algorithm.